A word gets part of its meaning from its surroundings. The Spanish word “gustado” appears in both “La película me ha gustado” and “La película no me ha gustado”: “I liked the movie” and “I did not like the movie.” To distinguish these sentences at their final word, we need to retain something of the sequence leading up to it.
A recurrent neural network, or RNN, follows that idea: each word is processed together with the state left by earlier words. The calculation produces a new state, which passes to the next step. The network reuses the same operation throughout the sentence; the current word and accumulated context change.
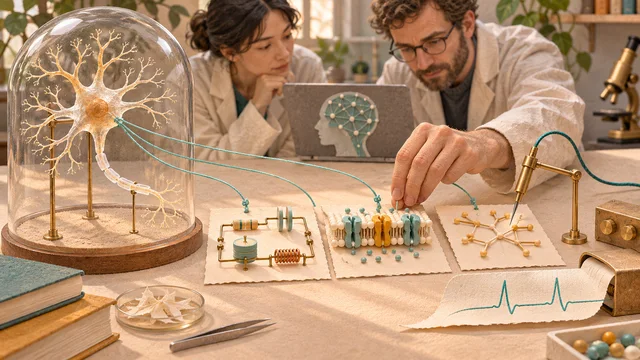
In this instrument, three needles make the three state values visible. Every word can update them. By the time “gustado” arrives, the previous state differs between the two sentences, and that difference participates in the output calculation. The same operation applies to every word, including “no”.
We can test the role of context by disconnecting the memory return: the cable highlighted with a turquoise halo, beside the three small gauges. Select it, then choose “Disconnect memory”. Each word is then calculated independently, and both sentences produce the same result at “gustado”. Comparing these conditions reveals what the connection between steps contributes.
This is a small teaching instrument. Its weights were trained once, locally, on 32 synthetic sentences that include the two we will explore. It lets us inspect how an RNN combines input and previous state; correctly classifying these known examples does not demonstrate language understanding. Everything runs in your browser, without training during the visit or calls to an AI service.
Two sentences to start with
Choose “No negation” and select the displayed words in order, from “la” to “gustado”. The selected word also appears above the machine. This lets you follow the sequence and observe what changes at each step.
The three needles show the three components of its hidden state: a numerical representation of the context read so far. A new word triggers a new state calculation; the needles move to its values and then settle. Some changes can be small. There is no rule requiring every needle to move noticeably at every word.
At “gustado”, the sentence is complete and the result is positive. Choose “With negation” to try the second sentence, which includes “no”. The first two words produce identical states because the prefix is identical. “No” changes the subsequent trajectory, and the final classification becomes negative.
You do not have to start at the beginning every time. Selecting a word recalculates the prefix through that word from an initial zero state. The result does not depend on which tokens you visited previously. At the end, the needles retain their final calculated state.
The cyan needle belongs to the selected sentence. The dashed amber reference shows the other sentence at the same word. The rows above the machine show the words read in each history. These are two runs compared on the same gauges, not two memories inside the network.
Select “me”: it follows “la película” in one sentence and “la película no” in the other. The references separate because their previous contexts differ. At “no” there is no reference: that word is absent from the other sentence. Disconnect the memory return and select “me” or “gustado” again: cyan and amber overlap, because the same word is calculated without its history.
What the machine retains
An RNN combines the current input with a fixed-size state from the previous step. It produces a new state of the same size. Here that vector contains three numbers. The three gauges on the MEMORY plate form one selectable assembly: Network memory. Their needles represent those three values.
“Hidden” distinguishes this internal representation from the input words and output classification. It does not mean we cannot inspect it. Nor does each needle necessarily have an independent human interpretation: we cannot label one “negation” and another “opinion” merely by watching them move.
Jeffrey Elman’s “Finding Structure in Time” provides a foundation for reusing internal activations as context. State values pass between steps; the learned weights stay fixed.
The feeder represents input, the central module represents the shared calculation, and the display represents output. Select a physical part to separate it and read its explanation. The casing and electronic components are a visual metaphor rather than the hardware that executes an RNN.
The vocabulary cartridge lets you inspect the 13 words and their encodings. Selecting a word inside it changes that inspection only; it does not feed the word into the sentence. The contacts in the drawing continue to show the actual word being processed.
The Previous state module, with three small gauges, retains the values just before the selected word. Open it to compare those values with the current state or go back one word. These are additional views of the same three units, not extra neurons.
The return conduit, identified by its turquoise halo, represents information returning to the processor. A pulse travels along it when advancing, except on the first step, whose previous state is zero. Its description lets you disconnect and reconnect context. Both output lamps stay off until the last word, then show the positive or negative classification.
Turning words into numbers
This example has a closed vocabulary of 13 Spanish words. Each word becomes a vector with one active position and zeros elsewhere: a one-hot encoding. “Película” keeps its accent in the interface; its internal identifier is “pelicula”.
The recurrent operation is:
hₜ = tanh(Wₓ xₜ + λ Wₕ hₜ₋₁ + b)
xₜ encodes the current word, hₜ₋₁ contains the previous three activations, and hₜ contains the new ones. Wₓ maps words to hidden units; Wₕ mixes the previous state; b adds learned biases. tanh keeps activations between −1 and 1. The PyTorch RNN documentation describes the same basic operation.
In the formula, λ represents the connection you can enable or disable through the return conduit. This removes recurrence for a teaching comparison. It is not a learned gate and does not turn this model into an LSTM. Reading with memory enabled uses one.
The output combines the hidden state with learned weights: sₜ = wᵧ · hₜ + bᵧ. Its final sign selects positive or negative sentiment. The result indicator’s description shows tanh(sₜ / 2), preserving that sign. We show the classification only after the whole sentence: training supervises complete sentences, not individual prefixes.
Removing the context
Select the cable with the turquoise halo, beside the Previous state module, then “Disconnect memory”. Its halo turns grey to indicate that the return is disconnected. Previous-state influence becomes zero. Read both sentences through “gustado”. Open the previous-state register and compare the three activations in the “Now” column. They now match: the current word is identical and the recurrent term has been removed.
This does not mean the needles stop moving throughout the sentence. Without memory, different words can still produce different states. What disappears is dependence on earlier words. “Me” can move the needles after “no” even though that calculation no longer retains “no”.
For these weights, both sentences finish with the same negative classification when memory is disabled. This is an intervention on a model trained with recurrence, not a separately trained classifier without it. The experiment demonstrates loss of the distinction, rather than promising accurate predictions after altering the calculation.
Selecting “Connect memory” restores previous-state influence to one, restoring the different final states and classifications. Changing this control recalculates the selected prefix from the initial state; it does not splice together two memory settings halfway through a sentence.
When the needles should move
The machine advances by words, rather than elapsed wall time. Selecting a word, changing the sentence or connecting and disconnecting memory can produce a different target state. Smooth movement between values is a visual transition, not additional model steps.
After settling, the needles must remain still until another change. After the last word, they retain their final state. Selecting the same token again must not invent a different state. Without recurrence, the same word in two contexts must yield identical readings.
Separating a part changes its location in the drawing, without modifying activations or weights. That distinction separates interaction with the representation from interaction with the calculation.
What this example does not demonstrate
The training data combines four sentence beginnings, four verbs and the presence or absence of “no”: 32 artificial sentences with labels assigned by a simple rule. Both displayed sentences belong to that set. Correctly classifying them verifies this example; it does not demonstrate generalization to new movie reviews.
We have not evaluated irony, complex negation, new vocabulary or long sentences. This English article uses the same Spanish inputs and the same model, with supporting translations; it is not a bilingual model. Reading a sentence updates state, not parameters. All inference happens locally in the browser.
Simple RNNs also have known difficulties learning long dependencies, discussed by Pascanu, Mikolov and Bengio in “On the difficulty of training Recurrent Neural Networks”. A needle moving very little is not a measurement of a vanishing gradient: we are inspecting forward activations rather than training gradients.
The useful claim here is narrower: the same final word can produce different states when its preceding context changes. Remove that context, repeat the reading and the difference disappears. That observable comparison explains recurrence without attributing understanding to a machine because its drawing contains three gauges.
Found this useful? If you would like to support this space, you can buy me a coffee.
Buy me a coffee Optional support through PayPal. You choose the amount.